 Fundamentals Hub
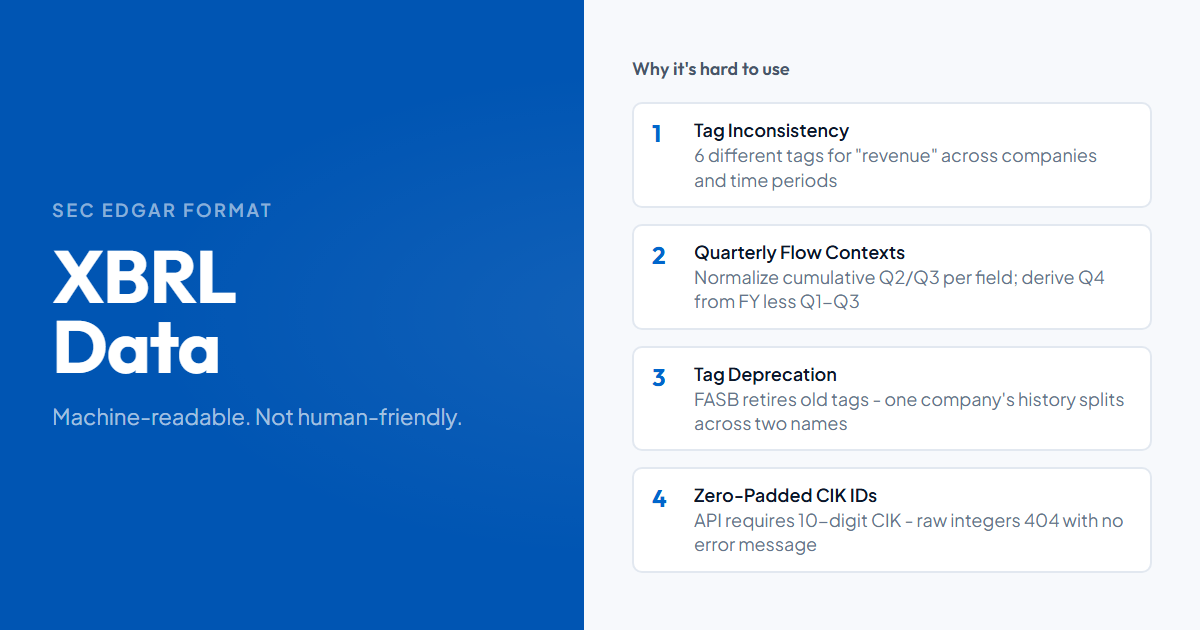
The SEC EDGAR API is free, well-documented, and covers every US public company. The problem arrives after your first successful request.
Pull Apple's company facts endpoint:
curl -H "User-Agent: YourApp admin@yourapp.com" \
  "https://data.sec.gov/api/xbrl/companyfacts/CIK0000320193.json"
The response is a JSON file tens of megabytes in size. You start looking for revenue. There's no "revenue" key. There's Revenues, SalesRevenueNet, RevenueFromContractWithCustomerExcludingAssessedTax, and a dozen more tags with overlapping data. Apple used SalesRevenueNet through FY2018, then adopted RevenueFromContractWithCustomerExcludingAssessedTax from Q1 FY2019 when ASC 606 took effect. The file doesn't tell you this. That's the XBRL data problem: the format is technically machine-readable, but interpreting it accurately requires knowledge that lives outside the file.
XBRL data is the structured layer underneath every SEC filing for US public companies. This post covers what it is, how it's organized, why the tag inconsistency problem is harder than it looks, and what realistic options exist for working with it. This is the underlying problem that the SEC EDGAR API guide assumes you understand.
What XBRL Is and Why the SEC Uses It
- XBRL
- eXtensible Business Reporting Language. A markup standard for financial data, mandated by the SEC since 2009 for US public company filings.
- US GAAP Taxonomy
- The FASB-maintained dictionary of thousands of XBRL elements covering financial concepts. Companies select tags from this taxonomy when filing.
- Tag Inconsistency
- The core XBRL problem: different companies use different tags for the same financial concept, and the same company switches tags over time.
- Company Facts Endpoint
- The SEC EDGAR API endpoint returning every XBRL-tagged fact for a single company across all filings.
XBRL (eXtensible Business Reporting Language) is a markup standard for financial data. The SEC mandated it starting in 2009 for large accelerated filers, phasing requirements across company sizes through 2011. The goal was to make financial filings machine-readable: instead of income statements locked in PDFs, companies would tag each data point with a standardized label so software could extract and aggregate it.
The standard is maintained by XBRL International. The financial vocabulary is defined by FASB's US GAAP Taxonomy, a dictionary of thousands of predefined elements covering nearly every financial concept. A company filing a 10-K tags its revenue line with one element, its net income with another, its total assets with a third. The SEC collects all these tagged facts and exposes them through public APIs that any developer can query at no cost.
In theory, this creates a layer of structured financial data across the entire universe of US public companies. In practice, the "standardized labels" are far less uniform than the mandate implies.
Inside a Company Facts JSON
The primary access point for XBRL data is the company facts endpoint:
https://data.sec.gov/api/xbrl/companyfacts/CIK0000320193.jsonTwo details to notice immediately: the URL uses CIK, not ticker symbol, and the CIK must be zero-padded to 10 digits. Apple's CIK is 320193, but the API requires CIK0000320193. Using the raw numeric CIK returns a 404. This trips up nearly every developer encountering the SEC API for the first time.
The response structure looks like this:
{
  "facts": {
    "us-gaap": {
      "RevenueFromContractWithCustomer...": {
        "label": "Revenue from Contract with Customer...",
        "units": {
          "USD": [
            { "end": "2024-09-28", "val": 391035000000,
              "accn": "0000320193-24-000123", "form": "10-K",
              "filed": "2024-11-01", "frame": "CY2024" }
          ]
        }
      }
    },
    "dei": {
      "EntityCommonStockSharesOutstanding": { ... }
    }
  }
}
The response has two namespaces. The us-gaap namespace contains financial statement tags from the US GAAP Taxonomy, revenue, net income, total assets, and everything else from the three financial statements. The dei namespace (Document and Entity Information) contains standardized disclosures required in every filing: entity name, CIK, fiscal year end, shares outstanding as of the filing date.
Within each tag, the data is an array of every instance that tag was reported across the company's filing history. Each entry includes the period end date, the reported value, the accession number of the filing, and the form type (10-K, 10-Q, 8-K). For a company with 20 years of SEC filings, a single tag might have dozens of entries.
The Tag Inconsistency Problem
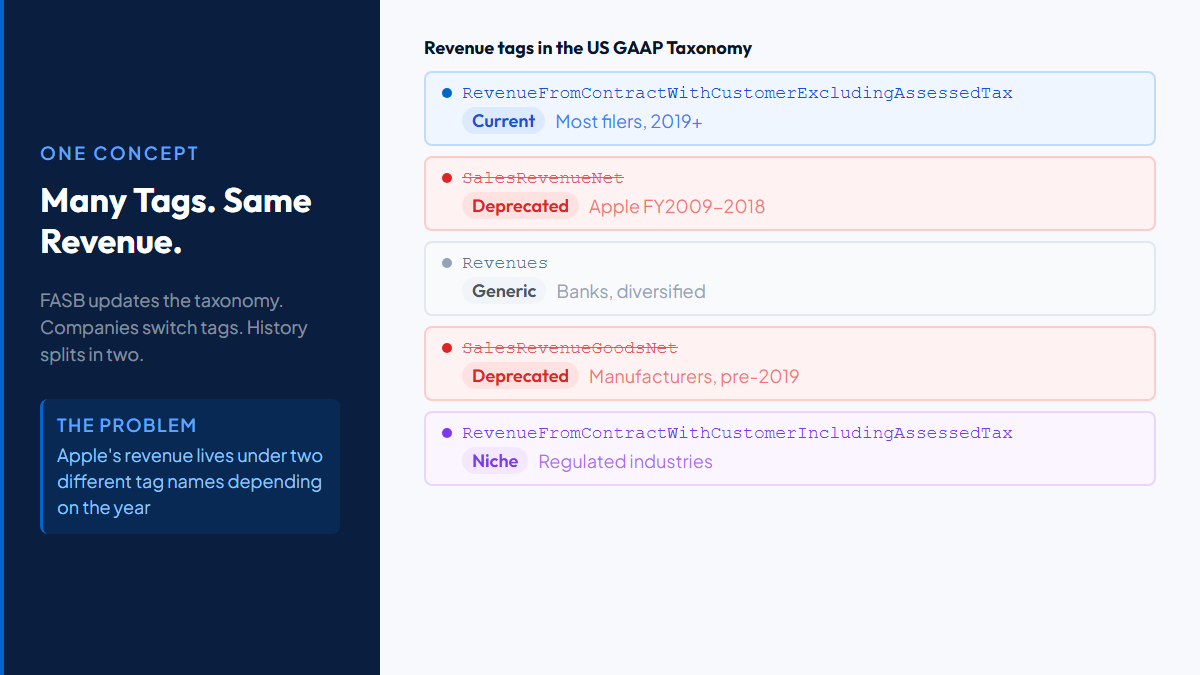
The US GAAP Taxonomy is a vocabulary, not a single agreed-upon word. For revenue, companies legitimately use different tags depending on their business model and the accounting standards in effect when they filed:
| Tag | Context |
|---|---|
Revenues | General broad tag, used by many companies |
SalesRevenueNet | Pre-ASC 606 standard, superseded by ASC 606 (effective for public companies from FY2019) |
RevenueFromContractWithCustomerExcludingAssessedTax | Post-ASC 606 standard, dominant since 2019 |
RevenueFromContractWithCustomerIncludingAssessedTax | Some regulated industries |
SalesRevenueGoodsNet | Goods-only revenue (manufacturing focus) |
None of these tags is "wrong." Each is technically precise. The problem is that different companies choose different ones for the same economic concept, and the same company switches tags when accounting standards change, without any flag in the data to indicate the transition.
A concrete example: a company that used SalesRevenueNet through FY2018 might switch to RevenueFromContractWithCustomerExcludingAssessedTax following ASC 606 adoption. If your code queries only the newer tag, you get revenue starting in 2019 with no error and no warning, just a missing decade of history. If you query only the older superseded tag, you get 2009-2018 and nothing recent.
Building a complete historical series requires more than a priority-ordered fallback list. Filter annual candidates to full-year durations. Keep semantic priority except for two scope proofs: (1) an exact-zero priority FY with another positive full-year revenue candidate (negative revenue is not zero); or (2) only when the nonnegative priority candidate does not reconcile, a reconciling alternative whose Q1-Q3 subtotal exceeds the priority FY. Otherwise keep priority. Maintaining that mapping and reconciliation logic as FASB releases new taxonomy versions is an ongoing task, not a one-time setup.
Four More Things That Make XBRL Hard at Scale
Quarterly flow facts can be YTD instead of standalone. A 10-Q may contain a quarter-only fact, a cumulative YTD fact, or both for the same field and end date. Prefer the quarter-duration fact when it exists. Otherwise derive Q2 from Q2 YTD minus Q1, and Q3 from Q3 YTD minus Q2 YTD. There is no Q4 10-Q, so derive each additive Q4 flow as the 10-K FY value minus Q1, Q2, and Q3. Balance sheet items are point-in-time snapshots and must not be subtracted.
Unit declarations vary across filings. Facts can be declared in a range of units (USD, USD/shares, shares, pure). The SEC normalizes all monetary values to absolute numbers in their declared unit, so there is no separate scale flag in the response. Read the units map in the JSON to know what each fact represents.
Tag transitions create split histories. When a new accounting standard supersedes an older tag, companies adopt the replacement in future filings while historical filings remain under the old tag. A company that filed 10-Ks for 15 years might have its revenue split between two tag names with no overlap. A robust normalization layer needs to know these tag lineages.
The dei namespace requires separate handling. EntityCommonStockSharesOutstanding (in dei) and CommonStockSharesOutstanding (in us-gaap) both represent shares outstanding, but they're different disclosures with different reference dates. For per-share calculations like EPS, using the dei value introduces a date mismatch.
What Normalized XBRL Data Looks Like
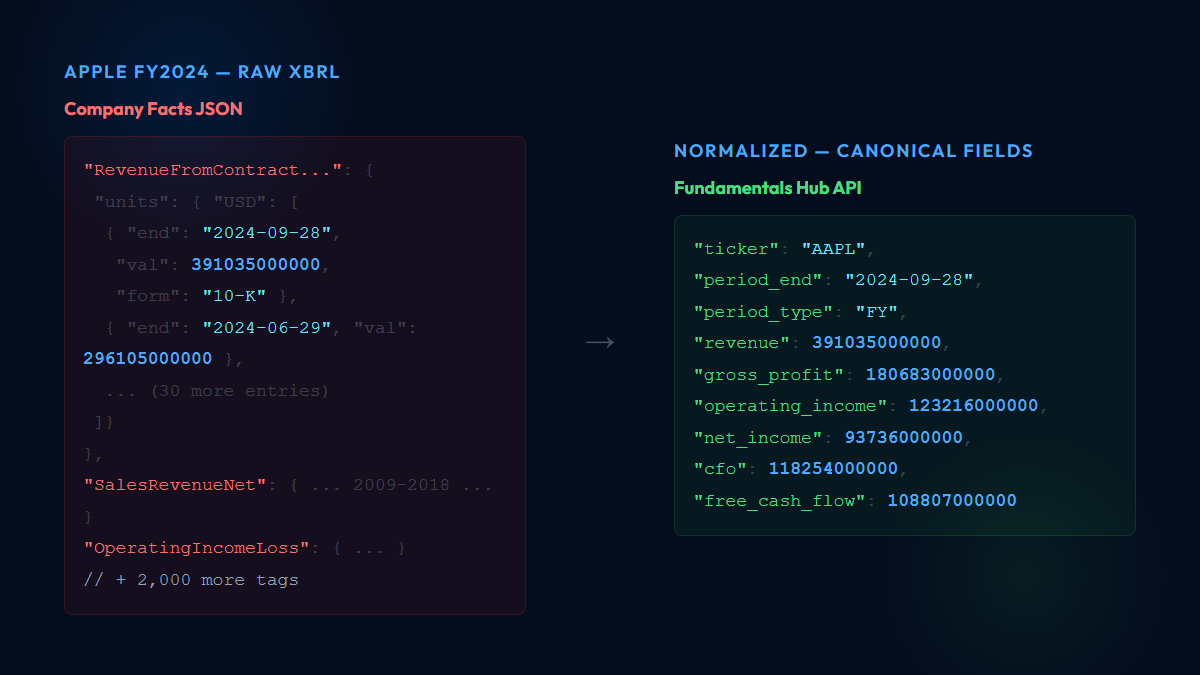
After tag and series resolution, YTD-to-quarter conversion, unit normalization, and period selection, what you actually want is a response like this:
{
  "cik": 320193,
  "ticker": "AAPL",
  "period_end": "2024-09-28",
  "period_type": "FY",
  "source_form": "10-K",
  "revenue": 391035000000,
  "gross_profit": 180683000000,
  "operating_income": 123216000000,
  "net_income": 93736000000,
  "cfo": 118254000000,
  "capex": 9447000000,
  "free_cash_flow": 108807000000,
  "total_assets": 364980000000,
  "total_equity": 56950000000
}
Instead of thousands of tags of varying relevance, 23 canonical fields, each derived from the correct tag for that company and period. No YTD conversion required. No unit scale lookup. No superseded tag handling.
(Fundamentals Hub returns this format for every company, with provenance fields showing exactly which XBRL tags populated each value. If you want to verify a figure against the raw filing, the source is always visible.)
Two Ways to Work With XBRL Data
Parse it yourself. The SEC makes all company facts available as individual company endpoints or as a bulk download (updated nightly). Building a production-grade XBRL parser means maintaining tag mappings plus cross-concept series reconciliation for each canonical field, implementing YTD subtraction, normalizing units, deduplicating facts when companies file amendments, and handling the edge cases above. The result is defensible, fully custom, and takes several weeks to build correctly. Maintaining it as FASB updates the taxonomy is ongoing work.
Use a normalized API. Financial data APIs that sit on top of SEC EDGAR have already solved the tag mapping and edge cases. For derived metrics like free cash flow and EBITDA (covered in the EBITDA explainer), the computation is pre-done. You get the clean field without needing to know whether the company used DepreciationDepletionAndAmortization or DepreciationAndAmortization for its D&A line.
The SEC EDGAR API guide covers how to pull raw XBRL data from the company facts endpoint directly.
Fundamentals Hub normalizes XBRL data from SEC EDGAR for 8,000+ companies across annual, quarterly, and TTM periods. You can try the free tier here.